API rate limits cap how many calls a client may make in a given time window, and the moment you integrate a third-party API, that cap becomes a contract you have to honor. The single most useful thing you can do is make your client limit-aware: read the rate headers the server sends, respect them before you get a 429, and apply exponential backoff with jitter when you do. Vendors like OpenAI document this pattern directly, and RFC 6585 standardizes the status code behind it.
TL;DR:
- Most APIs enforce multiple layers of limits, including rate limits, quotas, and concurrency caps, which often stack and are enforced independently.
- Vendor-specific headers like X-RateLimit-Remaining and Retry-After help clients monitor and adapt to limits, but they vary and require careful, defensive parsing.
- Using exponential backoff with jitter before retrying prevents synchronized request bursts that could overwhelm the server during throttling.
- Implement internal thresholds to decrease request rates proactively and monitor remaining quotas to avoid unexpected 429 responses.
- Quotas control usage over longer periods like days or months, while spike arrest or token buckets are better for smoothing sudden traffic bursts.
Table of Contents
- What Are Rate Limits, Quotas, and Concurrency Limits?
- Why Rate Limits Matter for Stability, Cost, and Security
- How Rate Limiting Works: Token Bucket, Leaky Bucket, and Windows
- How Servers Signal Limits and How Clients Should Read Them
- Client-Side Practices That Prevent and Recover From Throttling
- Quotas, Spike Arrest, and Choosing the Right Control
- Testing and Debugging Throttling Issues
- A Practical Example: Designing Limits for Production Automations
- The One Mindset Shift That Matters
- FAQ
- Sources
- Authoritative Docs and Standards to Consult Next
What Are Rate Limits, Quotas, and Concurrency Limits?
A rate limit restricts how many requests a client can send in a defined time window, such as 100 requests per minute. A quota is a longer-horizon allotment, often daily or monthly, that resets on a schedule rather than continuously. Concurrency limits cap how many requests can be in flight at once, regardless of how fast they arrive. These three controls often stack: you might have a per-minute rate limit, a monthly quota, and a concurrency ceiling of five simultaneous connections, each enforced independently.
Rate limits also come in two flavors. A hard limit rejects any request past the threshold with no exceptions. A soft limit allows temporary overages, sometimes with a warning or a grace period, before enforcement kicks in. Salesforce describes this distinction clearly: soft limits tolerate short bursts above the stated ceiling, while hard limits reject the request outright with a 429 response, and paid tiers often unlock higher allowances through account or billing consoles.
When you read vendor documentation, you will run into a handful of common metrics:
- RPS (requests per second): used for high-frequency, low-latency APIs like payment processing or real-time data feeds.
- RPM (requests per minute): the most common unit for general-purpose APIs and web services.
- TPM (tokens per minute): specific to language model APIs, where cost scales with the size of the input and output, not just the request count.
Knowing which metric governs your integration tells you whether to optimize for request count, payload size, or both.
Why Rate Limits Matter for Stability, Cost, and Security
Rate limits exist because shared infrastructure has finite capacity, and one noisy client can degrade service for everyone else. A single runaway loop making thousands of requests a second can exhaust database connections, saturate network bandwidth, or trigger cascading failures across dependent services. Limits keep access fair across all consumers of an API.
They also double as a security control. OWASP lists unrestricted resource consumption as a recognized API security risk, and rate limiting is one of the primary mitigations: without it, an attacker can drain compute budgets, flood logs, or mount a denial-of-service attack using nothing more than a basic script.
Finally, limits tie directly to cost and billing. Many APIs meter usage against a paid plan, so a rate limit or quota is effectively a spending control.
- Resource protection: limits prevent any one client from monopolizing shared backend capacity.
- Abuse mitigation: limits blunt scripted attacks, credential-stuffing attempts, and scraping bots before they cause damage.
- Cost control: limits and quotas map usage to billing tiers, so a misconfigured script does not generate an unexpected invoice.
How Rate Limiting Works: Token Bucket, Leaky Bucket, and Windows
Most rate limiters are built on one of four algorithms, and each makes a different trade-off between burst tolerance and smoothness.
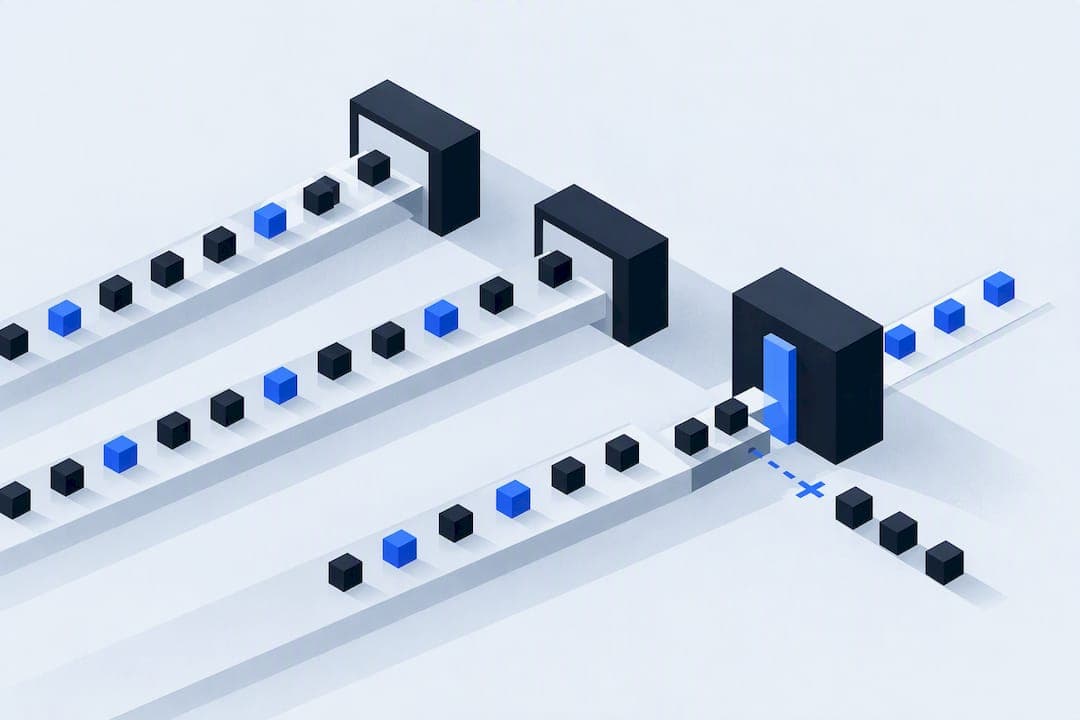
- Token bucket. A bucket holds a fixed number of tokens, refilled at a steady rate. Each request consumes a token, and once the bucket is empty, requests are rejected or queued until tokens regenerate. This allows short bursts up to the bucket size while enforcing a long-run average rate, which is why it is the most common choice for public APIs.
- Leaky bucket. Requests enter a queue and are processed at a fixed, steady rate regardless of how fast they arrive. Unlike token bucket, leaky bucket smooths output deterministically, trading burst tolerance for predictability, which suits systems that need a constant downstream load.
- Fixed window. The server counts requests in discrete time blocks, such as per calendar minute. It is simple to implement but has an edge case: a client can send a full window's worth of requests at the end of one window and another full batch at the start of the next, doubling the effective rate for a brief moment.
- Sliding window. This counts requests over a rolling interval rather than a fixed clock boundary, which avoids the fixed window's boundary spike but requires more state and computation to track.
Many production systems combine methods: a token bucket for burst tolerance layered with a concurrency limit that caps simultaneous in-flight requests, so a client cannot open hundreds of parallel connections even if it has tokens to spare.
Pro Tip: If your traffic is bursty by nature, like batch jobs or webhook replays, token bucket will frustrate you less than fixed window; if you need predictable downstream load, leaky bucket is the better fit.
How Servers Signal Limits and How Clients Should Read Them
When a client exceeds its limit, the server should return 429 Too Many Requests, a status code defined by RFC 6585 specifically for this purpose. The response should also carry a Retry-After header telling the client how long to wait before trying again.
Beyond the 429 itself, well-behaved APIs expose headers proactively on every response, not just on failures:
X-RateLimit-Limit: the total allowance for the current window.X-RateLimit-Remaining: how many requests are left before you hit the ceiling.X-RateLimit-Reset: when the window resets, usually as a timestamp or seconds remaining.Retry-After: how long to wait before retrying, sent specifically on 429 or 503 responses.
Vendor headers are not standardized. OpenAI exposes separate headers for request-based and token-based limits since a single call can exceed either ceiling, while Cloudflare uses its own Ratelimit header alongside Retry-After. Parse defensively: check for the header's presence before trusting its value, fall back to a conservative default delay when a header is missing or malformed, and log which specific limit was hit (requests, tokens, or concurrency) so your retry logic responds to the right constraint instead of guessing.
One IETF draft proposes a standardized RateLimit header syntax to resolve this inconsistency across vendors. Until that draft is finalized and widely adopted, treat header names and formats as vendor-specific and verify them against the docs for each API you integrate.
Client-Side Practices That Prevent and Recover From Throttling
Good client behavior starts before you ever see a 429. Here is the sequence that holds up in production.
- Monitor headers proactively. Read
X-RateLimit-Remainingon every response and slow down once you cross a threshold, say 10% of your allowance, instead of waiting for the server to reject you. Stripe recommends exactly this: treat limits as maximums to avoid, not targets to hit. - Back off exponentially, with jitter. Double your wait time after each failed attempt, but add randomness to that delay. Without jitter, every client that got throttled at the same moment retries at the same moment again, which synchronizes the next wave of requests and can knock the endpoint over a second time, an effect commonly called the thundering herd problem.
- Cap retries and total elapsed time. Set a hard ceiling on both the retry count and the cumulative time spent retrying a single operation, so a transient outage does not turn into an indefinite hang.
- Avoid double retries. If your SDK already retries eligible 429 or 503 responses automatically, as OpenAI's client libraries do, disable your own retry wrapper or coordinate the two so you do not multiply wait times unintentionally.
- Batch where the API allows it. Combining multiple operations into a single request amortizes overhead, and for token-metered APIs it can increase throughput without increasing request count.
Beyond retries, build visibility into your usage. Surface remaining-quota metrics on a dashboard and fire an alert when any client approaches its ceiling, well before it starts failing requests. Dynamic concurrency control, where a client reduces parallel requests when remaining capacity drops, catches problems that static retry logic misses entirely.
Pro Tip: Keep a per-client adaptive throttle rather than a single global retry policy. A client hammering one high-traffic endpoint should slow itself down independently of clients calling lighter endpoints.

Quotas, Spike Arrest, and Choosing the Right Control
Quotas and rate limits solve different problems, and conflating them leads to the wrong fix. A quota is a renewable allotment, often tied to billing or entitlements, like a monthly cap on API calls for a given pricing tier. Azure API Management's quota policy lets you configure calls, bandwidth, and a renewal period, and returns a 403 with a Retry-After header once the quota is exhausted.
A rate limit, by contrast, is about runtime smoothing, protecting live capacity second by second or minute by minute. Spike arrest policies sit closer to the rate-limit side: they flatten short, sharp traffic bursts without affecting the client's longer-term allotment.
- Use quotas when the goal is entitlement or billing enforcement over days or months.
- Use spike arrest or token buckets when the goal is protecting live infrastructure from sudden traffic bursts.
- Scope matters: a quota or limit can apply per user, per project, or per organization, and that scope determines who gets throttled when traffic spikes. Google Cloud's
quotaUserparameter, for example, lets you assign quota at a finer grain than the default API key.
Testing and Debugging Throttling Issues
When requests start failing with 429s, work through this checklist rather than guessing at a fix.
- Reproduce safely. Run load tests against a staging environment or a vendor's designated sandbox, never production traffic, and check whether the vendor offers batch or bulk endpoints that reduce call volume for testing scenarios.
- Read the headers on the failing response. Identify exactly which limit fired: request count, token count, or concurrency. The header names will tell you, and OpenAI's docs recommend snapshotting these headers during testing so you can replay realistic reset and
Retry-Aftersequences in staging. - Simulate throttling deliberately. Mock a 429 response with a known
Retry-Aftervalue and confirm your client waits the correct amount of time, caps its retries, and logs the event instead of silently hanging. - Collect telemetry on every attempt. Log request timing, the full header snapshot, the client or user identifier making the call, and the retry trace. This turns a one-off incident into a dataset you can use to tune thresholds later.
A client that passes this checklist in staging rarely surprises you in production.
A Practical Example: Designing Limits for Production Automations
When we build done-for-you automations, every integration that touches a third-party API gets its own documented retry and rollback plan before it goes live. For high-value operations, like writing a new lead into a customer record or triggering an AI voice follow-up, conservative internal quotas are set well below the vendor's published ceiling, so a traffic spike never risks the client's standing with that vendor.
- Least-privilege access: each automation only holds the API scopes it needs, nothing broader.
- Explicit consent flows: any workflow that calls an external API on a client's behalf is documented, so there is a written record of what talks to what.
- Monitoring thresholds: remaining-quota metrics are tracked per integration, with escalation paths defined before a limit is ever approached.
- Rollback plans: every build includes a documented way to pause or revert an automation if a third-party API changes its limits or behavior unexpectedly.
That documentation is what makes the difference between an automation that degrades gracefully and one that silently breaks.
The One Mindset Shift That Matters
Most teams treat rate limits as an annoyance to route around. The better frame is to treat them as a contract, and a useful one: they tell you, in advance, exactly how your integration will behave under stress, which is more than most of your own code can promise.
Three things to do this week: audit which headers your current integrations actually read, add exponential backoff with jitter anywhere it is missing, and set an alert for remaining quota before you ever see a 429. If building that instrumentation into a production automation feels like more than your team has bandwidth for, it is the kind of scoped, documented work we take on for service businesses directly.
— Felix
FAQ
What Are API Rate Limits?
API rate limits cap the number of requests a client can send to a server within a specific time window, such as 100 requests per minute. They protect shared infrastructure, prevent abuse, and often tie directly to a vendor's pricing tiers.
How Do I Fix an "API Rate Limit Exceeded" Error?
Read the Retry-After header on the 429 response and wait at least that long before retrying. Implement exponential backoff with jitter for subsequent attempts, and check whether you are hitting a request-count limit, a token limit, or a concurrency limit, since the fix differs for each.
How Do I Rate Limit an API to 10 Requests per Minute?
Use a token bucket with a capacity of 10 tokens that refill fully every minute, or a sliding window counter that rejects any request once 10 have been counted in the trailing minute. Token bucket is usually simpler to reason about and tolerates short bursts better than a fixed window.
How Long Is Too Long for an API Call?
There is no universal threshold since acceptable duration depends on the specific API and its documented timeout behavior. Check the vendor's own timeout and rate-limit documentation, since some count a long-running request against concurrency limits even before it completes.
Sources
- OpenAI: Rate limits
- Salesforce help: overview of limits
- Azure API Management: quota policy
- OWASP API Security: Unrestricted resource consumption
Authoritative Docs and Standards to Consult Next
Start with your vendor's own rate-limit page for exact numbers and headers, then check RFC 6585 for 429 semantics. Developer platforms with layered quota scoping, like MedScrub, are also worth reviewing for policy design patterns.